Motion vectors
Every inter-frame codec has already searched for the displacement of each macroblock in
order to compress the video. These two functions read that work back out instead of doing
it again: motionvectors() draws it, motionvectordata() returns it as numbers.
Drawing them
motionvectors() renders the vectors as arrows over the video, via ffmpeg's codecview
filter. It is a decoder-level view of motion with nothing recomputed, and it needs only
ffmpeg.
Only codecs that carry motion vectors will show anything. Intra-only formats—MJPEG,
common in .avi files—have none.
Reading them as data
motionvectordata() returns one row per decoded frame: the time, the picture type, how
many vectors the frame carried, an area-weighted magnitude, and the typical displacement
median_dx / median_dy of the blocks that moved.
It is cheap in a way that differencing pixels is not. On a 103-minute recording, decoding took 2.2 s and decoding with the vectors took 2.7 s, against 27 minutes to compute frame-differenced quantity of motion over the same file.
Filter by picture type. This is the difference between a usable signal and a poor one. Measured against exact quantity of motion on a 100-minute corpus:
| frames used | r |
|---|---|
| P-frames only | 0.87 |
| each type standardised, then pooled | 0.70 |
| everything pooled | 0.54 |
B-frames are about three quarters of the frames, and their vectors point both ways over
varying temporal distances, so they are not measuring the same quantity. Keeping only
picture_type == 'P' leaves roughly 12.6 Hz on 50 fps footage, which is ample for anything
at the scale of a gesture.
It measures the encoder, not the scene. An encoder may choose any vector that predicts a block cheaply, so on flat or still regions the vectors mean little. Across 18 windows of six recordings the correlation with quantity of motion had a median of 0.82—but 0.86 in windows with motion in them, against 0.57 in windows without. A re-encoded proxy carries its proxy encoder's decisions, not the camera's.
source gives the direction of the reference, never the distance. It is plus or minus
one even when the encoder predicted from four frames back, so multi-frame predictions read
as multiples of the true per-frame displacement. On a block moving 4 pixels per frame, 53
per cent of vectors came back as 4 and the rest as 8 or 16. The medians are robust to this;
magnitude, being a sum, is not, and is best treated as a quantity to correlate against
itself over time rather than as pixels per second.
Looking at a lot of material quickly
motionvectoroverview() is the one to reach for first on unfamiliar video. It produces
one sheet per recording from a single decode, carrying the three kinds of
representation a first pass wants:
- spatial—the area motion covered, coloured by direction, and again as plain amount
- temporal—motion across the whole recording, the curve to scrub against
- spatio-temporal—horizontal and x-motiongrams, where a body crossing the room draws a diagonal
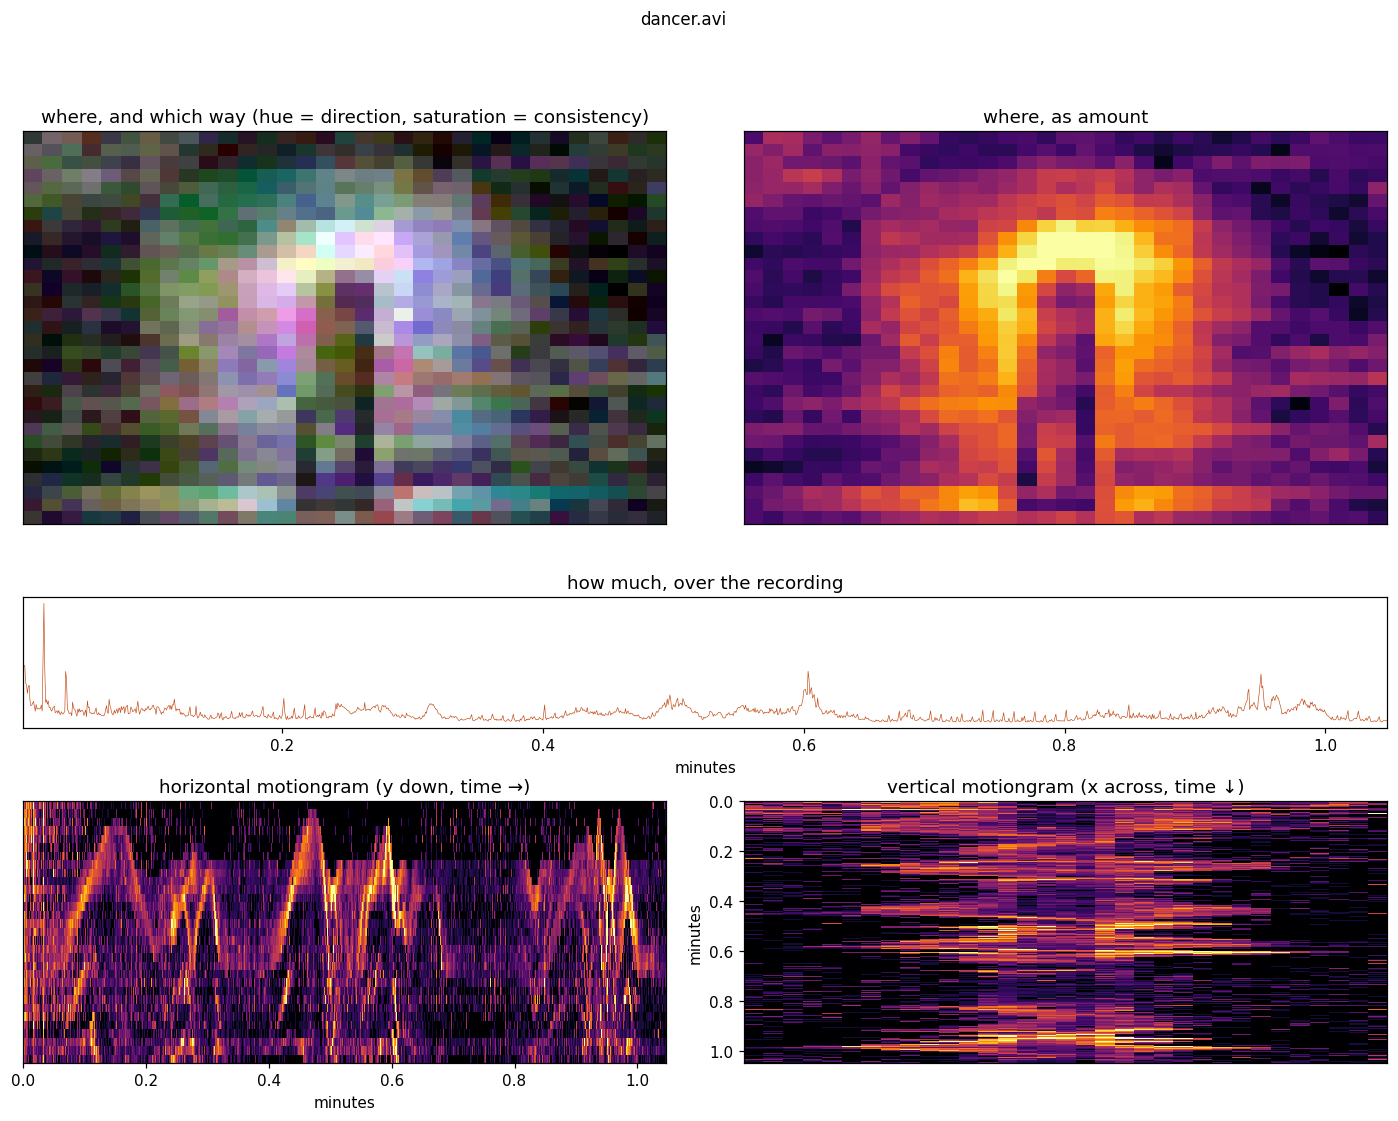
The bundled dancer.avi on one sheet. The amount map draws the arc the arms swept
around a body that never moved its feet, and the motiongrams carry the same dance in
the classic orientations: the y-motiongram runs time rightward and holds the
arm oscillations, since this dance is vertical movement, and the x-motiongram
runs time downward with the room's width across.
About five minutes for a 100-minute 1920x1080 recording, against roughly twenty-four for
the same views computed one at a time, because decoding is nearly the whole cost and each
separate view opens the file again. Every array is on the returned figure's .data, so the
same pass can feed further analysis without decoding twice.
In the direction panel, hue is the bearing, value is how much motion there was, and saturation is directional coherence—how consistently that part of the room moved one way. Grey means "moved, but not in any one direction", which is the honest description of most of a room during improvisation. Coherence is under-sampled above about 1.5 Hz on 50 fps footage, since P-frames arrive at roughly a quarter of the frame rate: right for a body crossing a room, wrong for a shaking hand.
Every timescale at once
motionscape() draws the quantity of motion at every timescale at once: a triangle
whose base row is the motion in short windows, each row above a longer window, and the
apex one window covering the whole recording. The construction comes from Craig Sapp's
keyscapes, which do the same for tonality.
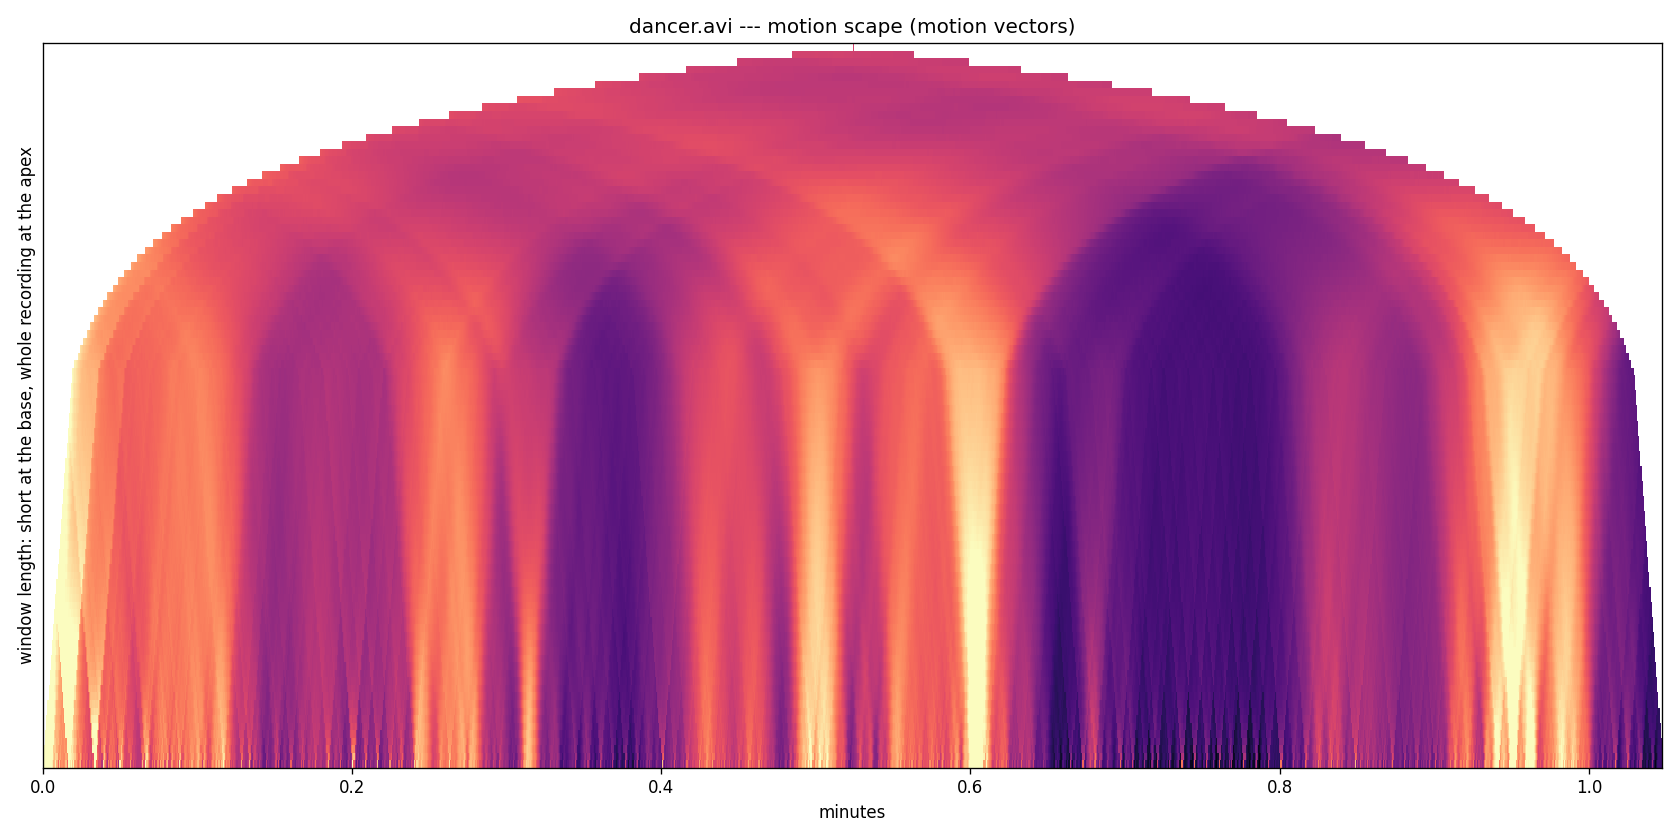
The bundled dancer.avi: bright columns at the base are single bursts, the dark mass
around 0.7--0.8 minutes is a stretch of stillness long enough to survive widening
windows, and the arches show where neighbouring episodes merge.
It answers a question the flat curve cannot: at what scale does this recording stop looking like one thing? Evenly continuous material is flat all the way up. A few busy patches separated by quiet stay separate at the base and merge into one mass higher up, and the height at which they merge is the length of the structure joining them.
It is a real triangle: each row is only as wide as the number of places a window that long can sit, and the narrowing is the information rather than a cosmetic frame.
Nothing in it assumes motion vectors. Pass track= any per-frame series—mg_motion's
QomRaw, or a qom.f4 read off disk—to scape a frame-differenced quantity of motion
instead. Built from a cumulative sum, so the cost does not grow with window length.
Reproducibility
Frame-threaded decoding drops motion vectors, and not the same ones twice. Three identical runs over one clip returned 28,702, 29,649 and 29,975 vectors with threading on, and 29,975 every time with it off.
On a real 1920x1080 recording the loss is 222 vectors in 25.7 million—0.0009 per cent,
far below anything that changes a reading—and threading is about 4.5 times faster, so it
is the default. Pass deterministic=True to anything in this module when a result has to
reproduce exactly.
Which files this works on, measured
One 120 s window of real dancing, re-encoded every way, comparing the vectors against the frame difference of that same file, and timing both.
Codec decides whether it works at all. ffmpeg exports motion vectors for H.264 and
MPEG-4 Part 2 and, in this build, nothing else—HEVC and VP9 decode perfectly and return
zero vectors, so the result is all zeros with no error. motionvectordata warns when a
file carries none, because zeros otherwise read as stillness.
| codec | r (P-frames) | vectors |
|---|---|---|
| H.264 | 0.82 | yes |
| MPEG-4 Part 2 | 0.72 | yes |
| HEVC | — | none exported |
| VP9 | — | none exported |
| MJPEG | — | none (intra-only) |
Resolution barely matters, which is the useful part. The vectors are computed on macroblocks, so the cost scales with area but the agreement does not.
| width | r (P-frames) | vector cost | framediff cost | speed-up |
|---|---|---|---|---|
| 320 | 0.73 | 0.12 s | 1.11 s | 9× |
| 640 | 0.82 | 0.24 s | 2.21 s | 9× |
| 1280 | 0.80 | 0.88 s | 5.60 s | 6× |
| 1920 | 0.81 | 1.97 s | 11.57 s | 6× |
Frame rate helps. More P-frames means more of the signal, and at 50 fps the agreement with the source recording's own motion is much the better for it.
| fps | r (P-frames) | r against the 1920 source |
|---|---|---|
| 12 | 0.72 | 0.50 |
| 25 | 0.82 | 0.45 |
| 50 | 0.89 | 0.72 |
Compression quality hardly matters, and heavier compression is if anything better.
| CRF | r (P-frames) |
|---|---|
| 18 | 0.75 |
| 23 | 0.82 |
| 30 | 0.84 |
| 38 | 0.81 |
At high quality the encoder subdivides finely and spends vectors on detail that is not motion; at low quality it keeps large blocks that track the body. So a proxy is not a handicap here, which is worth knowing given how often analysis runs on one.
Across the whole sweep the vectors ran 5 to 25 times faster than differencing the same file, and pooled correlation stayed between 0.01 and 0.53 against 0.72--0.89 on P-frames alone—the single most important thing to get right.
Reading the vectors needs PyAV—pip install musicalgestures[motionvectors]. ffprobe
will say the side data is present but will not print it, and ffmpeg has no numeric dump, so
there is no command-line route. Drawing them is unaffected.
MgMotionVectorData
dataclass

MgMotionVectorData(time, picture_type, n_vectors, magnitude, median_dx, median_dy)
One row per decoded frame, as arrays.
picture_type is here because it decides whether the rest is usable. Measured on a
100-minute corpus against exact frame-differenced quantity of motion, the magnitude
below correlates at r = 0.87 on P-frames alone and r = 0.54 once B-frames are pooled
in, so a caller who ignores this field gets a much worse signal than the codec is
offering. Filtering to picture_type == 'P' costs three quarters of the frames and
is usually the right trade.
MgMotionVectorViews
dataclass

MgMotionVectorViews(history_weight, history_vx, history_vy, history_coherence, time, magnitude, motiongram_y, motiongram_x)
Every motion-vector view of one recording, from a single decode.
Three kinds of representation, which is what a first pass over unfamiliar material
wants: spatial (where motion happened, and which way), temporal (how much,
over time), and spatio-temporal (the motiongrams, position against time, in
the classic orientations: motiongram_horizontal as (rows, frames) with time
rightward, motiongram_vertical as (frames, cols) with time downward).
The temporal view is an envelope, not a track. magnitude against time is
the motion envelope at the encode's own reference cadence --- about 12.6 Hz on a
50 fps B-frame encode, not 50 Hz --- for roughly a tenth of a full decode's cost.
Measured against the exact frame-difference quantity of motion on a six-recording
dance corpus, it correlates at median r = 0.82 across windows, falling to 0.57
where little moves: the envelope is for finding structure, not for measuring
stillness. B-frames are excluded by default (p_frames_only=True) because their
future-referencing vectors pool badly; including them costs about 0.3 of r.
mg_motionvectors 
mg_motionvectors(self, target_name=None, overwrite=True)
Renders a video visualising the motion vectors encoded in the input video.
Inter-frame codecs (MPEG-1/2/4, H.264, H.265, …) store motion vectors that describe
how macroblocks move between frames. This method uses FFmpeg's codecview filter
(with -flags2 +export_mvs) to draw those vectors as arrows on top of the video,
giving a quick, decoder-level view of motion without any re-computation.
NB: Only codecs that actually carry motion vectors will show arrows. Intra-only
formats (e.g. MJPEG, common in .avi files) have none — convert to an inter-frame
codec first (e.g. via show(mode='notebook') which makes an mp4, or any mp4/h264
source) to see motion vectors.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
target_name
|
str
|
Target output name for the video. Defaults to None (which uses the input filename with the suffix "_motionvectors"). |
None
|
overwrite
|
bool
|
Whether to allow overwriting existing files or to automatically increment the target filename. Defaults to True. |
True
|
Returns:
| Name | Type | Description |
|---|---|---|
MgVideo |
MgVideo
|
An MgVideo pointing to the rendered motion-vector video. |
Source code in musicalgestures/_motionvectors.py
24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 | |
mg_motionvectordata 
mg_motionvectordata(self)
Read the motion vectors the codec already computed, as numbers rather than arrows.
motionvectors() renders these as a video to look at. This returns them as data, and
the difference in cost is the point: an inter-frame codec has already searched for the
displacement of every macroblock, so reading its answer is close to free, while
differencing pixels does the same search again in Python. On a 103-minute recording,
decoding took 2.2 s and decoding with the vectors took 2.7 s, against 27 minutes for
the frame-differenced quantity of motion.
What it is not. The vectors are the encoder's decisions, not a measurement of the scene: an encoder is entitled to any vector that predicts the block cheaply, and on flat or still regions it will pick one that has nothing to do with motion. The result tracks quantity of motion well where there is motion to track and poorly where there is not --- on that same corpus, median r = 0.86 in windows with motion and 0.57 in windows without. Re-encoded proxies carry their proxy encoder's vectors, not the camera's.
Vectors are normalised to point forward in time. A B-frame may predict a block
from a later frame, which reverses the sign; dividing by the vector's source
corrects that, so a block moving right reads as positive whichever way it was
predicted. Without it a B-frame's vectors point backwards half the time and averaging
them gives roughly nothing.
The reference distance is corrected from the cadence, with two residuals.
source records only the direction, plus or minus one, never how many frames away
the reference was, so the distance is recovered instead from the picture-type
cadence: past-referencing vectors are divided by the display-order gap to the
previous reference frame, which makes a P-frame after a run of B-frames read
per-frame displacement rather than the whole span's. What the cadence cannot see:
blocks reaching an OLDER reference through multi-reference prediction --- measured
on a block moving 4 pixels per frame, such blocks read as 8 or 16 with source at
plus or minus one throughout --- and B-frame vectors pointing at a future
reference, which default filtering excludes. So median_dx and median_dy are
medians for a reason and are robust to the residuals; magnitude is a sum and
inherits what remains of the over-count. Treat magnitude as a quantity to
correlate against itself over time, which is what it was validated for, rather
than as pixels per second.
Returns:
| Name | Type | Description |
|---|---|---|
MgMotionVectorData |
MgMotionVectorData
|
|
MgMotionVectorData
|
|
|
MgMotionVectorData
|
quantity to compare against quantity of motion), and |
|
MgMotionVectorData
|
(the typical displacement in pixels of the blocks that moved --- taken over |
|
MgMotionVectorData
|
every block instead, these would report the still background's zero however fast |
|
MgMotionVectorData
|
the one moving thing was going). Frames with no vectors, which includes every |
|
MgMotionVectorData
|
intra frame, read as zero throughout. |
Raises:
| Type | Description |
|---|---|
ImportError
|
if PyAV is not installed. ffprobe reports that the side data exists but will not print the vectors themselves, and ffmpeg has no numeric dump, so there is no route to these numbers through the command line. |
Source code in musicalgestures/_motionvectors.py
83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 203 204 205 206 207 208 209 210 211 212 213 214 215 216 217 218 219 220 221 222 223 224 225 226 227 228 229 230 231 232 233 234 235 | |
motion_vector_grid 
motion_vector_grid(filename, deterministic=False, threshold=0.0)
Per-frame displacement fields at macroblock resolution, yielded one at a time.
Everything spatial in this module is built on this: the history image sums it over time, the motiongrams reduce it along one axis per frame, the waterfall bins those. Decoding is the expensive part, so it happens once per view rather than once per frame of interest.
A generator, and that is not a style choice. The first version returned the frames stacked into arrays of shape (frames, rows, cols). On a 100-minute 1920x1080 recording that is 310,368 frames over a 68 by 120 grid --- 20 GB per array, and it built three. It ran on every clip in the test suite and would have exhausted memory on the first real recording. Consumers now accumulate as they go, and nothing holds more than one frame's grid.
The grid is the codec's own macroblock lattice --- typically 16 pixels, sometimes 8 or 4 within the same frame when the encoder subdivides. Vectors are painted into the cells their block covers, so a 16x16 block contributes to all of its cells and the result does not favour finely-subdivided regions for having more vectors.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
threshold
|
float
|
Drop vectors shorter than this many pixels. The
counterpart of |
0.0
|
Yields:
| Name | Type | Description |
|---|---|---|
tuple |
|
|
|
shaped (rows, cols). |
||
|
|
Source code in musicalgestures/_motionvectors.py
238 239 240 241 242 243 244 245 246 247 248 249 250 251 252 253 254 255 256 257 258 259 260 261 262 263 264 265 266 267 268 269 270 271 272 273 274 275 276 277 278 279 280 281 282 283 284 285 286 287 288 289 290 291 292 293 294 295 296 297 298 299 300 301 302 303 304 305 306 307 308 309 310 311 312 313 314 315 316 317 318 319 320 321 322 323 324 325 326 327 328 329 330 331 332 333 334 335 336 337 338 339 340 341 342 343 344 345 346 347 348 349 350 351 352 353 354 355 356 357 358 359 360 361 362 363 364 365 366 367 368 | |
accumulate_motion_vectors 
accumulate_motion_vectors(filename, p_frames_only=True, deterministic=False, threshold=0.0)
The whole space motion happened in, summed over the recording.
Returns (weight, vx, vy, coherence): how much motion each cell saw, the
direction it saw on average, and how consistently that direction held.
P-frames only by default. A B-frame's vectors are referenced over varying temporal distances, and pooling them into a spatial average blurs the direction that is the reason for accumulating vectors rather than frame differences.
Source code in musicalgestures/_motionvectors.py
371 372 373 374 375 376 377 378 379 380 381 382 383 384 385 386 387 388 389 390 391 392 393 394 395 396 397 398 399 400 401 402 403 404 405 406 407 408 409 410 411 412 413 414 415 416 417 418 419 420 421 | |
mg_motionvectorhistory 
mg_motionvectorhistory(self, mode='direction', colormap='inferno', gamma=0.5, target_name=None, overwrite=True)
The whole space the motion happened in, accumulated from the codec's vectors.
motionhistory() renders the Bobick--Davis image from frame differences and encodes
recency; heatmap() accumulates where pixels changed. Neither can say which way
anything went, because a frame difference has no sign --- somebody entering a region
and leaving it look identical. A motion vector is a displacement, so this can, and
that is the reason for it to exist.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
mode
|
str
|
|
'direction'
|
colormap
|
str
|
Matplotlib colormap, used by |
'inferno'
|
gamma
|
float
|
Applied to the accumulated amount before colouring, so that a few violent moments do not leave everything else black. Defaults to 0.5. |
0.5
|
target_name
|
str
|
Output path. Defaults to the input name with
|
None
|
overwrite
|
bool
|
Defaults to True. |
True
|
Returns:
| Name | Type | Description |
|---|---|---|
MgImage |
MgImage
|
the rendered image, at the video's own dimensions. |
Notes
Built from P-frames only, for the reason given on motionvectordata. And the
vectors are the encoder's decisions: over a region with no detail every candidate
predicts equally well, so the encoder copies whatever its neighbours used and the
field there is inherited rather than observed. Expect that wherever the picture is
flat.
Source code in musicalgestures/_motionvectors.py
424 425 426 427 428 429 430 431 432 433 434 435 436 437 438 439 440 441 442 443 444 445 446 447 448 449 450 451 452 453 454 455 456 457 458 459 460 461 462 463 464 465 466 467 468 469 470 471 472 473 474 475 476 477 478 479 480 481 482 483 484 485 486 487 488 489 490 491 492 493 494 495 496 497 498 499 500 501 502 503 504 505 506 507 | |
motion_vector_motiongrams 
motion_vector_motiongrams(filename, p_frames_only=True, deterministic=False, threshold=0.0)
The two classic motiongrams from the vectors, named for the picture.
The HORIZONTAL motiongram is the wide picture: each frame's grid collapsed across
its columns to a y-profile, stacked so time runs rightward and vertical position
down. The VERTICAL motiongram is the tall picture: each frame collapsed down its
rows to an x-profile, stacked so time runs downward and horizontal position across.
A body crossing the room draws a diagonal in the vertical gram; a body rising or
falling draws one in the horizontal. The orientations and names are the ones
motiongrams() has always used.
Returns:
| Name | Type | Description |
|---|---|---|
tuple |
|
Source code in musicalgestures/_motionvectors.py
510 511 512 513 514 515 516 517 518 519 520 521 522 523 524 525 526 527 528 529 530 531 532 533 534 535 536 537 538 | |
mg_motionvectorgrams 
mg_motionvectorgrams(self, colormap='inferno', gamma=0.5, max_width=4000, target_name=None, overwrite=True)
Motiongrams built from the codec's motion vectors.
The same view motiongrams() gives, at a fraction of the cost, because the
displacement has already been computed by the encoder. The trade is resolution: this
is drawn on the macroblock lattice, sixteen pixels, and on P-frames only, so on 50 fps
footage it carries about 12.6 columns per second rather than 50.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
colormap
|
str
|
Matplotlib colormap. Defaults to |
'inferno'
|
gamma
|
float
|
Applied before colouring so quiet passages stay visible. Defaults to 0.5. |
0.5
|
max_width
|
int
|
Longest the saved image's TIME axis may be, in pixels --- across the horizontal image, down the vertical one. One point per P-frame is right for the array and wrong for the picture: a 158-minute session has 77,592 of them, and stretching that to the video's height gave a 149-megapixel PNG of 309 MB for something meant to be glanced at. Points are pooled by taking the maximum, not the mean, so a brief accent still shows in a column standing for several seconds. Defaults to 4000. |
4000
|
target_name
|
str
|
Output path; the two images take |
None
|
overwrite
|
bool
|
Defaults to True. |
True
|
Returns:
| Name | Type | Description |
|---|---|---|
MgList |
MgList
|
the y-motiongram and the x-motiongram, in that order, in the classic |
MgList
|
orientations --- y wide with time rightward, x tall with time downward. |
Source code in musicalgestures/_motionvectors.py
541 542 543 544 545 546 547 548 549 550 551 552 553 554 555 556 557 558 559 560 561 562 563 564 565 566 567 568 569 570 571 572 573 574 575 576 577 578 579 580 581 582 583 584 585 586 587 588 589 590 591 592 593 594 595 596 597 598 599 600 601 602 603 604 605 606 607 608 609 610 611 612 613 614 615 | |
motion_vector_profiles 
motion_vector_profiles(filename, n_samples=40, axis='horizontal', p_frames_only=True, deterministic=False, threshold=0.0)
Motion profiles at n_samples moments, for stacking as a waterfall.
Each profile is one spatial axis of the vector grid, summed over the other, pooled over the frames nearest that moment rather than taken from a single frame --- a single P-frame's vectors are sparse, and a waterfall of sparse profiles reads as noise where the pooled version reads as a body moving.
Returns:
| Name | Type | Description |
|---|---|---|
tuple |
|
Source code in musicalgestures/_motionvectors.py
618 619 620 621 622 623 624 625 626 627 628 629 630 631 632 633 634 635 636 637 638 639 640 641 642 643 644 645 646 647 648 649 | |
mg_motionvectorwaterfall 
mg_motionvectorwaterfall(self, n_samples=40, axis='horizontal', cmap='viridis', dpi=200, elev=35, azim=-60, target_name=None, overwrite=True)
A waterfall of motion profiles, cascading through time.
The same cascade silhouette_waterfall() draws, but from displacement rather than
from a silhouette, so it needs no background subtraction and no pose model --- and it
shows where motion was, not where a body was. A dancer standing still has a
silhouette and no vectors.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
n_samples
|
int
|
How many profiles to stack. Defaults to 40. |
40
|
axis
|
str
|
|
'horizontal'
|
cmap
|
str
|
Matplotlib colormap, applied over time. Defaults to
|
'viridis'
|
dpi
|
int
|
Defaults to 200. |
200
|
elev, azim
|
float
|
3D view angles. Default to 35 and -60. |
required |
target_name
|
str
|
Output path. Defaults to the input name with
|
None
|
overwrite
|
bool
|
Defaults to True. |
True
|
Returns:
| Name | Type | Description |
|---|---|---|
MgFigure |
MgFigure
|
the rendered waterfall. |
Source code in musicalgestures/_motionvectors.py
652 653 654 655 656 657 658 659 660 661 662 663 664 665 666 667 668 669 670 671 672 673 674 675 676 677 678 679 680 681 682 683 684 685 686 687 688 689 690 691 692 693 694 695 696 697 698 699 700 701 702 703 704 705 706 707 708 709 710 | |
motion_vector_views 
motion_vector_views(filename, p_frames_only=True, deterministic=False, threshold=0.0)
Every view at once, in one decode.
The individual functions each decode the file, which is nearly all of the cost, so asking for four views costs four times what it needs to. This walks the vectors once and accumulates all of them. On a 100-minute 1920x1080 recording that is about four minutes rather than twenty-four.
The result is checked against the individual functions in the test suite rather than assumed equal to them, because a fast path that quietly disagrees with the slow one is worse than no fast path.
Source code in musicalgestures/_motionvectors.py
759 760 761 762 763 764 765 766 767 768 769 770 771 772 773 774 775 776 777 778 779 780 781 782 783 784 785 786 787 788 789 790 791 792 793 794 795 796 797 798 799 800 801 802 803 804 805 806 807 808 809 810 811 812 | |
mg_motionvectoroverview 
mg_motionvectoroverview(self, colormap='inferno', gamma=0.5, target_name=None, overwrite=True)
One sheet per recording, from one decode: where, how much, and when.
Built for a first look at unfamiliar material rather than for measurement. Hours of archive video, several representations per file, as the starting point for qualitative annotation --- so it favours covering the whole recording cheaply over resolving any part of it finely.
Five panels, of the three kinds a first pass wants:
- spatial --- the area motion covered, coloured by direction, and the same accumulation as plain amount;
- temporal --- motion over the whole recording, the curve to scrub against;
- spatio-temporal --- the y- and x-motiongrams, position against time, where a body crossing the room draws a diagonal.
Everything comes from the codec's own motion vectors, so the cost is close to the cost of reading the file: about five minutes for a 100-minute 1920x1080 recording, against roughly twenty-four for the same views computed one at a time, and far less than differencing the pixels.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
colormap
|
str
|
Matplotlib colormap for the amount panels. Defaults to
|
'inferno'
|
gamma
|
float
|
Applied before colouring so quiet passages stay visible. Defaults to 0.5. |
0.5
|
target_name
|
str
|
Output path. Defaults to the input name with
|
None
|
overwrite
|
bool
|
Defaults to True. |
True
|
Returns:
| Name | Type | Description |
|---|---|---|
MgFigure |
MgFigure
|
the sheet, with every underlying array in |
MgFigure
|
feed further analysis without decoding again. |
Source code in musicalgestures/_motionvectors.py
815 816 817 818 819 820 821 822 823 824 825 826 827 828 829 830 831 832 833 834 835 836 837 838 839 840 841 842 843 844 845 846 847 848 849 850 851 852 853 854 855 856 857 858 859 860 861 862 863 864 865 866 867 868 869 870 871 872 873 874 875 876 877 878 879 880 881 882 883 884 885 886 887 888 889 890 891 892 893 894 895 896 897 898 899 900 901 902 903 904 905 906 907 908 909 910 911 912 913 914 915 916 917 918 919 920 921 922 923 924 925 926 927 928 929 930 | |
motion_scape 
motion_scape(track, n_scales=64)
A Sapp-style scape of any per-frame track: every timescale at once.
In Craig Sapp's keyscape each row is a window length and each cell the key that best fits that window, so the plot answers "at what scale does this look like one thing" rather than "what is happening now". The same construction over quantity of motion reads the same way: a recording that is one long even stretch looks flat at every scale, and a few busy patches separated by quiet stay separate at the bottom and merge into one bright mass as the windows grow.
Rows run coarse to fine --- the top row is a single window covering the whole recording, the bottom row is the track itself --- which puts the apex at the top, as a keyscape has it.
Computed from a cumulative sum, so the cost does not depend on how wide the windows get: the whole plot is O(n_scales x n) whatever the recording's length.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
track
|
ndarray
|
One value per frame. Quantity of motion from either source works; nothing here assumes it came from motion vectors. |
required |
n_scales
|
int
|
How many window lengths to stack. Defaults to 64. |
64
|
Returns:
| Type | Description |
|---|---|
|
np.ndarray: shape (n_scales, len(track)), coarsest row first. Each cell is the |
|
|
mean of the track over a window of that row's length centred on that position, |
|
|
and NaN where a window that long does not fit --- which is what gives the plot |
|
|
its triangular shape, apex at the top. |
Source code in musicalgestures/_motionvectors.py
933 934 935 936 937 938 939 940 941 942 943 944 945 946 947 948 949 950 951 952 953 954 955 956 957 958 959 960 961 962 963 964 965 966 967 968 969 970 971 972 973 974 975 976 977 978 979 980 981 982 983 984 985 986 987 988 989 990 991 992 993 994 995 996 | |
mg_motionscape 
mg_motionscape(self, track=None, track_times=None, n_scales=96, colormap='magma', gamma=0.5, target_name=None, overwrite=True)
A scape of the recording's motion: every timescale in one triangle.
After Craig Sapp's keyscape, where each row is a window length and the apex is a single window covering the whole piece. Here each cell is the mean quantity of motion over that window, so the plot answers a question the flat curve cannot: at what scale does this recording stop looking like one thing? A session of even, continuous improvisation is flat all the way up. A session of separated bursts stays separated at the base and merges into one mass near the apex, and the height at which it merges is the length of the structure.
Parameters:
| Name | Type | Description | Default |
|---|---|---|---|
track
|
array - like
|
One value per frame to build the scape from. Pass
a frame-differenced quantity of motion here --- |
None
|
track_times
|
array - like
|
Seconds for each value in |
None
|
n_scales
|
int
|
Rows in the triangle. Defaults to 96. |
96
|
colormap
|
str
|
Defaults to |
'magma'
|
gamma
|
float
|
Applied before colouring. Defaults to 0.5. |
0.5
|
target_name
|
str
|
Output path. Defaults to the input name with
|
None
|
overwrite
|
bool
|
Defaults to True. |
True
|
Returns:
| Name | Type | Description |
|---|---|---|
MgFigure |
MgFigure
|
the scape, with the track and the triangle in |
Source code in musicalgestures/_motionvectors.py
999 1000 1001 1002 1003 1004 1005 1006 1007 1008 1009 1010 1011 1012 1013 1014 1015 1016 1017 1018 1019 1020 1021 1022 1023 1024 1025 1026 1027 1028 1029 1030 1031 1032 1033 1034 1035 1036 1037 1038 1039 1040 1041 1042 1043 1044 1045 1046 1047 1048 1049 1050 1051 1052 1053 1054 1055 1056 1057 1058 1059 1060 1061 1062 1063 1064 1065 1066 1067 1068 1069 1070 1071 1072 1073 1074 1075 1076 1077 1078 | |